
Shipping AI features without shipping a liability
Demos are easy. Production AI needs an eval set, guardrails, privacy rules, cost controls, and a fallback. A field guide from two AI products we shipped.
Zynitex Engineering
Product & engineering notes
The short answer
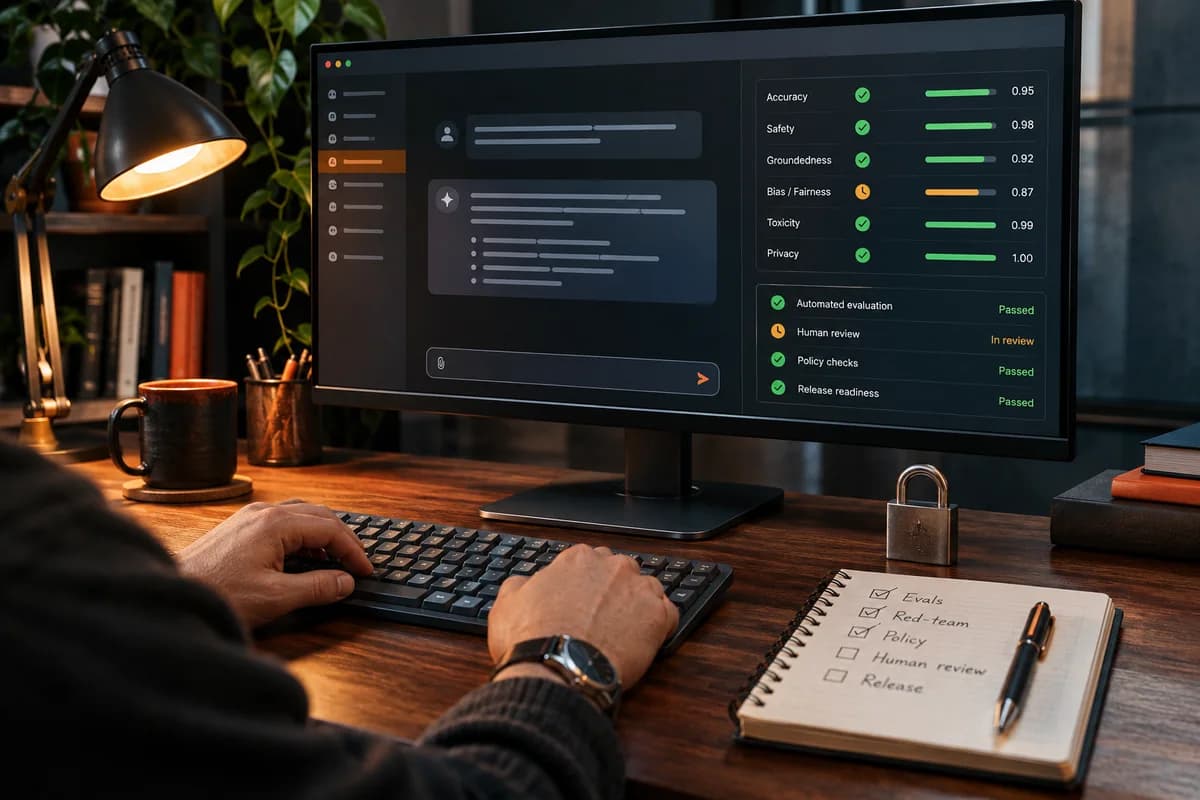
A production AI feature needs four things a demo does not: a narrow job, an evaluation set, guardrails around inputs and outputs, and a fallback when the model is slow, wrong, or unavailable. Add cost and privacy reviews before launch, not after.
What this note covers
- “Add AI” is not a job. Define the outcome in user terms.
- Build 50–200 real evaluation cases before tuning the prompt.
- Guardrails are a chain: input, model, output, and product.
- Streaming improves perceived latency; it doesn’t fix a slow backend.
- Sensitive data needs a data map, not a vendor promise.
On this page(11 sections)
- 01Pick a job, not a vibe
- 02Build the eval set before the prompt
- 03Context beats prompt cleverness
- 04Guardrails in four layers
- 05Latency and cost engineering
- 06Privacy is not a footer link
- 07Human-in-the-loop is a feature
- 08Observability and abuse
- 09A launch checklist
- 10What the model didn’t fix
- 11Earn the trust
The first AI demo takes an afternoon. The production version takes a quarter, and most of that isn’t the model.
We’ve shipped an AI health assistant in Solix and AI-assisted interview scoring in ElyteSpark. The model was rarely the bottleneck. The missing pieces were the job definition, the evaluation, and the support path for people who got a bad answer.
Pick a job, not a vibe
“Add AI” is not a job. “Turn a 40-minute mock interview into three specific improvements” is a job. The narrower the job, the easier it is to measure and the harder it is to fake.
- Turn a resume into five concrete edits, with the original line quoted.
- Score a practice interview against a published rubric and explain the score.
- Triage a support ticket into a category, priority, and missing information.
- Answer questions from a help centre with links to the source pages.
- Generate menu descriptions from a structured list of ingredients.
“Chat with your data” sounds impressive and is often a support burden. If users don’t know what to ask, the feature has no job.
Job
Narrow, measurable
Guardrails
Input + output
Model
Structured output
Human
Review + fallback
Eval
50–200 cases
Latency
p95 budget
Cost
per request
Privacy
data map
Build the eval set before the prompt
Fifty to two hundred real examples, including the ugly ones. Define what a good answer looks like. Then compare prompts and models against the same set. If you can’t reproduce a bad answer, you can’t fix it.
| Eval type | What it catches | How to run it |
|---|---|---|
| Golden set | Regressions on known cases | Fixed cases with expected facts and constraints |
| Rubric review | Tone, usefulness, completeness | Human review or a model judge with spot checks |
| Adversarial set | Prompt injection, PII, off-topic answers | Red-team cases and deliberate edge inputs |
| Online metrics | Real behaviour after launch | Accept rate, edit rate, escalation rate, thumbs-down |
| Cost and latency | Whether the feature is viable | p50 and p95 latency, tokens, retries, cache hit rate |
Track prompt version, model, temperature, and eval date. A spreadsheet is fine at the start. The discipline matters more than the tool.
Note
Evaluate the product, not just the model
A model can answer correctly and still produce a feature nobody trusts. Measure whether users accept, edit, or ignore the output.
Context beats prompt cleverness
RAG is not a magic prefix. It’s a retrieval product: chunking, metadata, freshness, permissions, citations, and a way to say “I don’t know”.
- Show source dates and links so users can verify.
- Enforce document permissions before retrieval, not after.
- Return an empty result with a clear message when nothing relevant is found.
- Reindex on publish and track stale documents.
- Keep prompts and retrieved context separate so you can debug them independently.
Guardrails in four layers
| Layer | Examples |
|---|---|
| Input | Size limits, PII redaction, injection checks, rate limits, allowed file types |
| Model | System instructions, structured output, tool allowlist, temperature limits |
| Output | Schema validation, safety filter, citation check, confidence threshold |
| Product | Preview, edit, undo, human review, AI disclosure, escalation path |
Guardrails are not a single regex. They’re a chain of decisions, and every layer needs logs. If the model returns invalid JSON, the product should fail closed or show a retry, not render a broken answer.
Latency and cost engineering
- Stream tokens to improve perceived latency.
- Route simple tasks to a smaller model and escalate only when needed.
- Cache deterministic answers and common retrieved contexts.
- Cap output tokens and request size.
- Batch offline jobs instead of making users wait.
- Set timeouts, retries with a budget, and a graceful fallback.
| Technique | Helps | Hurts |
|---|---|---|
| Streaming | Perceived latency | Error handling and partial outputs |
| Small model first | Cost and speed | Quality on hard cases |
| Caching | Repeat cost | Staleness and cache-key mistakes |
| Async job | Long-running work | No instant feedback |
| Long context | Fewer retrieval steps | Cost and distraction |
| Human review | Trust and accuracy | Operational cost |
Privacy is not a footer link
In health, education, and hiring, the data is sensitive even when a model vendor says it isn’t. Map what leaves your system, why, how long it’s retained, and who can access it.
- Collect only the data the job needs.
- Record consent and purpose where required.
- Review vendor terms for training, retention, and sub-processors.
- Redact logs before they reach an observability tool.
- Keep a deletion path for prompts, uploads, and generated outputs.
- Document cross-border processing.
Watch out
Don’t test prompts with real customer data
Pasting a candidate’s resume, a medical note, or a customer chat into a random AI tool is a data transfer, not a test. Use synthetic or consented samples.
Human-in-the-loop is a feature
Solix’s health assistant and ElyteSpark’s interview scoring both need a human-readable rationale and an easy correction path. The AI can draft; the person decides. That isn’t a lack of ambition. It’s how trust is built in categories where a wrong answer has consequences.
- Show what the answer is based on.
- Let the user edit before saving or sending.
- Provide an undo or dismiss action.
- Route low-confidence or high-risk cases to a person.
- Disclose when AI is involved.
Observability and abuse
- Log prompt version, model, latency, tokens, and cost per request.
- Use a trace ID that links the user action to the model call.
- Track refusal rate, validation failures, and thumbs-down feedback.
- Set spend caps and per-user rate limits.
- Keep a kill switch that disables the feature without a deploy.
- Watch for prompt injection and data exfiltration patterns.
A launch checklist
- Write the job in one sentence and the failure modes in another.
- Build an eval set with real edge cases.
- Choose a fallback before choosing a model.
- Add input, output, and product guardrails.
- Test with a mid-range phone and a slow connection.
- Review data flows and vendor terms.
- Set cost, latency, and error alarms.
- Write the support script for bad answers.
- Run a small cohort before a full launch.
- Decide what you will remove if the feature doesn’t earn its cost.
What the model didn’t fix
Gemini is capable enough for many product features. The failure cases are usually product failures: no clear job, no eval, no fallback, no support path. The model is rarely the reason a feature feels untrustworthy. The missing product decisions are.
Earn the trust
Treat AI like a new employee with a narrow brief, a probation period, and a manager. Give it context, check the work, limit the blast radius, and keep a human accountable. That’s less exciting than a demo. It’s also how the feature survives contact with real users.
Direct answers
Questions people actually ask
Short, checkable answers. Every entry here is also published as structured FAQ data for search and answer engines.
Which AI model should we use?
Start with one capable general model, build an eval set, and compare against a smaller or cheaper option. Don’t choose by benchmark alone. Measure quality on your actual job, plus latency and cost at the volume you expect.
Do we need RAG or a vector database?
Only if the job depends on your own documents or fresh data. If the task is scoring a structured input or rewriting a short text, retrieval may add complexity without value. Start without it and add retrieval when the failure cases show a context gap.
How do we stop hallucinations?
You can reduce them, not eliminate them. Constrain the output schema, provide source context, require citations, validate facts, set confidence thresholds, and route risky cases to a human. Always give the user a way to verify.
Can we use AI to write our blog?
You can use it to draft or edit, but publish only after human review, fact-checking, and adding first-hand experience. Undisclosed, unverified AI content is a brand and SEO risk, and it rarely reads like a person who has done the work.
References
Sources and further reading
Compliance notes are operational guidance, not legal or tax advice. Rules and thresholds change — confirm your position with a qualified professional.
Written by
Zynitex Engineering
We design and build the systems behind Zynibill, Invoice Studio, and client platforms like Regalia, Kristive, and ElyteSpark. These notes are the things we wish we had read before shipping them.
More about ZynitexKeep reading
Related notes
The LMS mistakes that only show up after launch
Role design, video delivery, progress semantics, payments, certificates, and student data. The decisions that determine whether an LMS survives its first cohort.
27 October 2026·10 minEngineeringNext.js performance in production: fix the 20% users feel
Field data instead of Lighthouse theatre. The hero image, client boundaries, third-party scripts, and caching decisions that change how a Next.js site feels.
29 September 2026·9 minBusinessWhen custom software is worth it (and when it’s an expensive hobby)
A decision framework with real economics: status-quo cost, three-year ownership, the 80% rule, hybrids, and the questions to ask before you sign.
15 September 2026·9 min